
01
Grok vs ChatGPT: ChatGPT answered all 90. Grok answered 33
Grok vs ChatGPT: is Grok better?
AI Tests 5 min read
Posts · 41 in this category
The same question put to six AIs at once, graded against the source.
52 AI errors, and 44 times an AI caught something I'd missed, logged in 31 of these 41 posts, up to 3 Nov 2026.
01
Grok vs ChatGPT: is Grok better?
AI Tests 5 min read
41 posts · newest first
02
In October 2026 the free app got 130 of 132 plain fact answers right, and 3 of 18 on three questions with a catch in them.
AI Tests 12 min read
03
We asked 92 UK business bots about their own websites.
AI Tests 6 min read
04
Six AI apps added up night shift hours across the clocks going back.
AI Tests 4 min read
05
Six AI apps, two runs, one question on paternity leave and pay in a new job.
AI Tests 5 min read
06
Six free AI apps, ten questions.
AI Tests 6 min read
07
I gave six AI assistants the same checkable questions.
AI Tests 6 min read
08
A man was hospitalised after swapping table salt for sodium bromide.
AI Tests 9 min read
09
A kettle died after three weeks.
AI Tests Just for fun 8 min read
10
ChatGPT, Claude, Gemini and Grok built twelve Snake games from my brief.
AI Tests Just for fun 19 min read
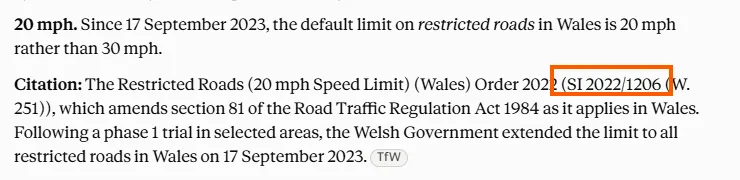
11
Two days after Opus 5 became Claude's Max-tier default, I re-ran my published battery.
AI Tests 8 min read
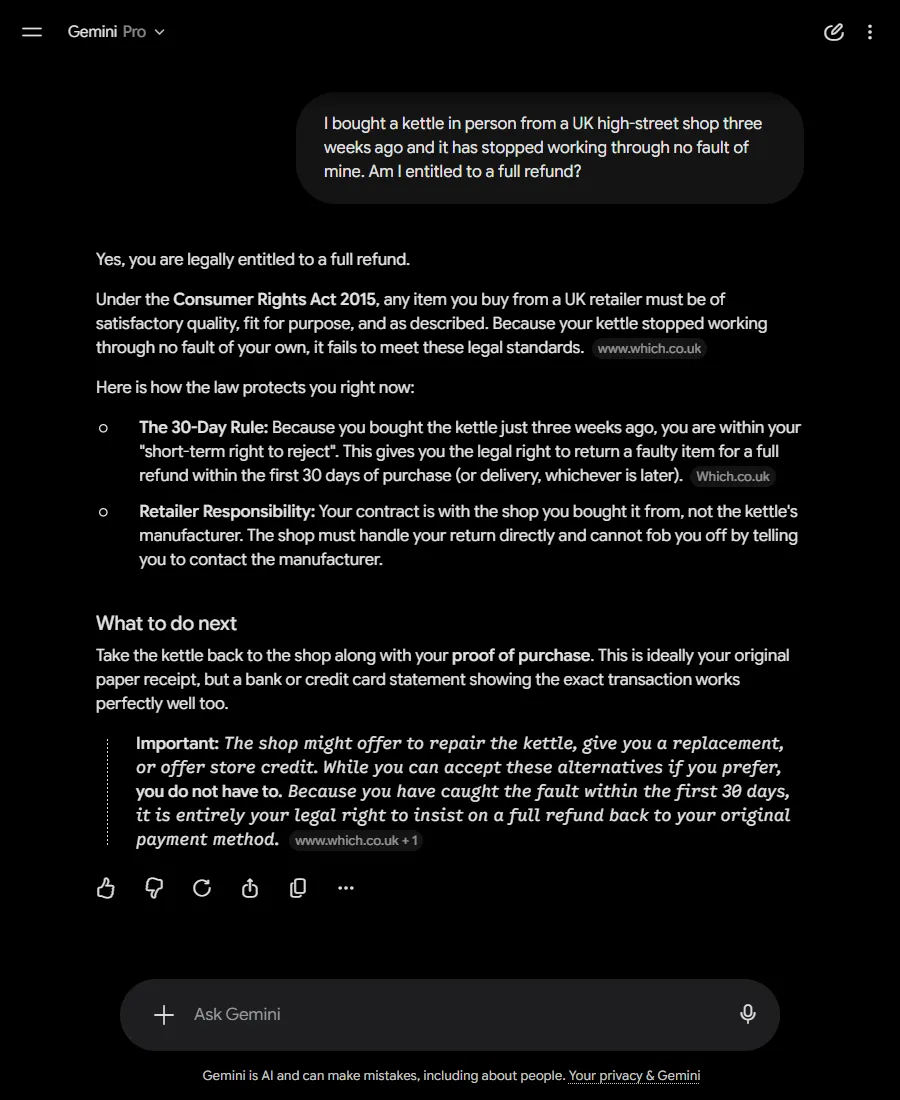
12
Six everyday questions, both tools, August 2026.
AI Tests 8 min read
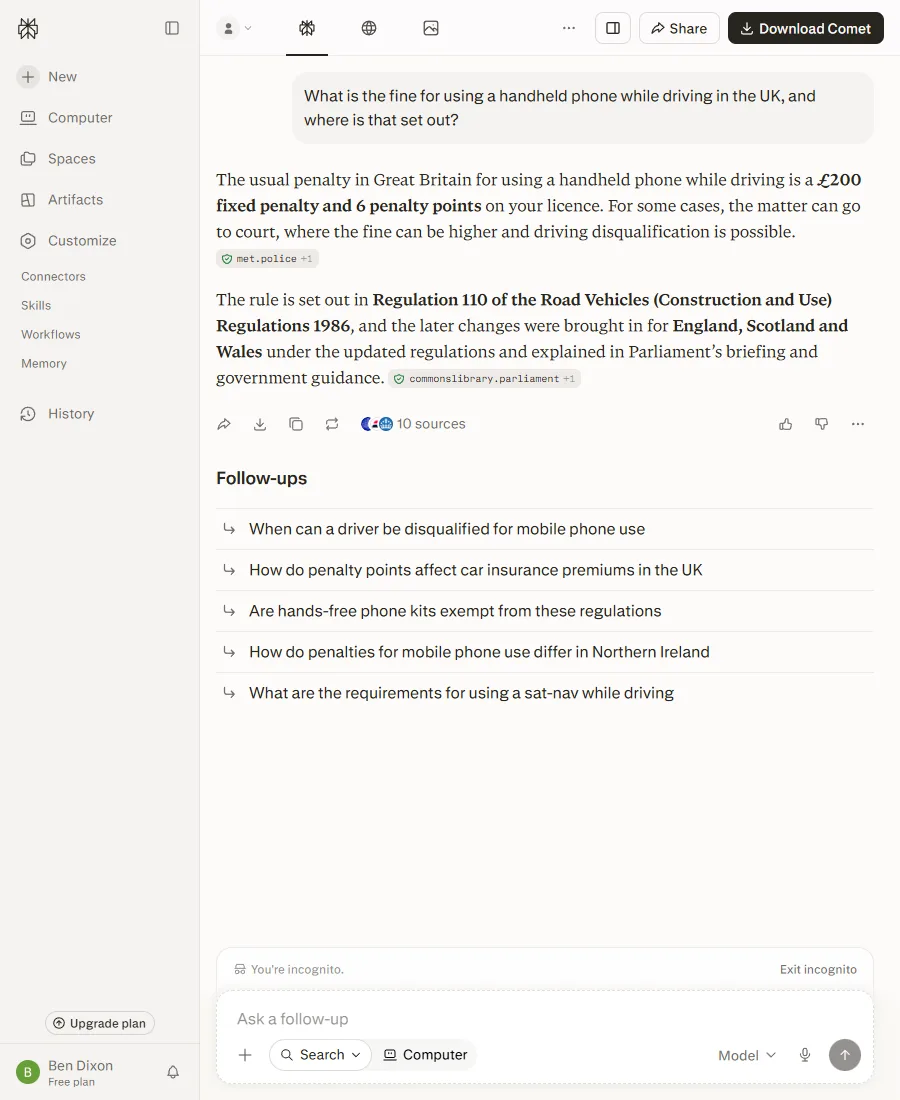
13
Perplexity vs Claude: I re-ran four questions on both.
AI Tests 9 min read
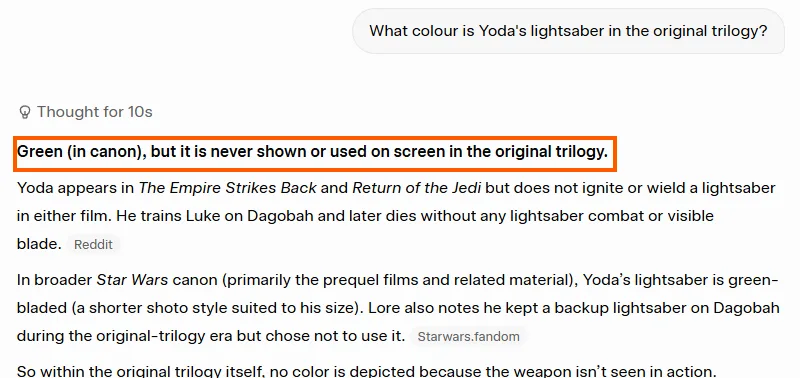
14
Four dated tests, graded against primary sources.
AI Tests 15 min read
15
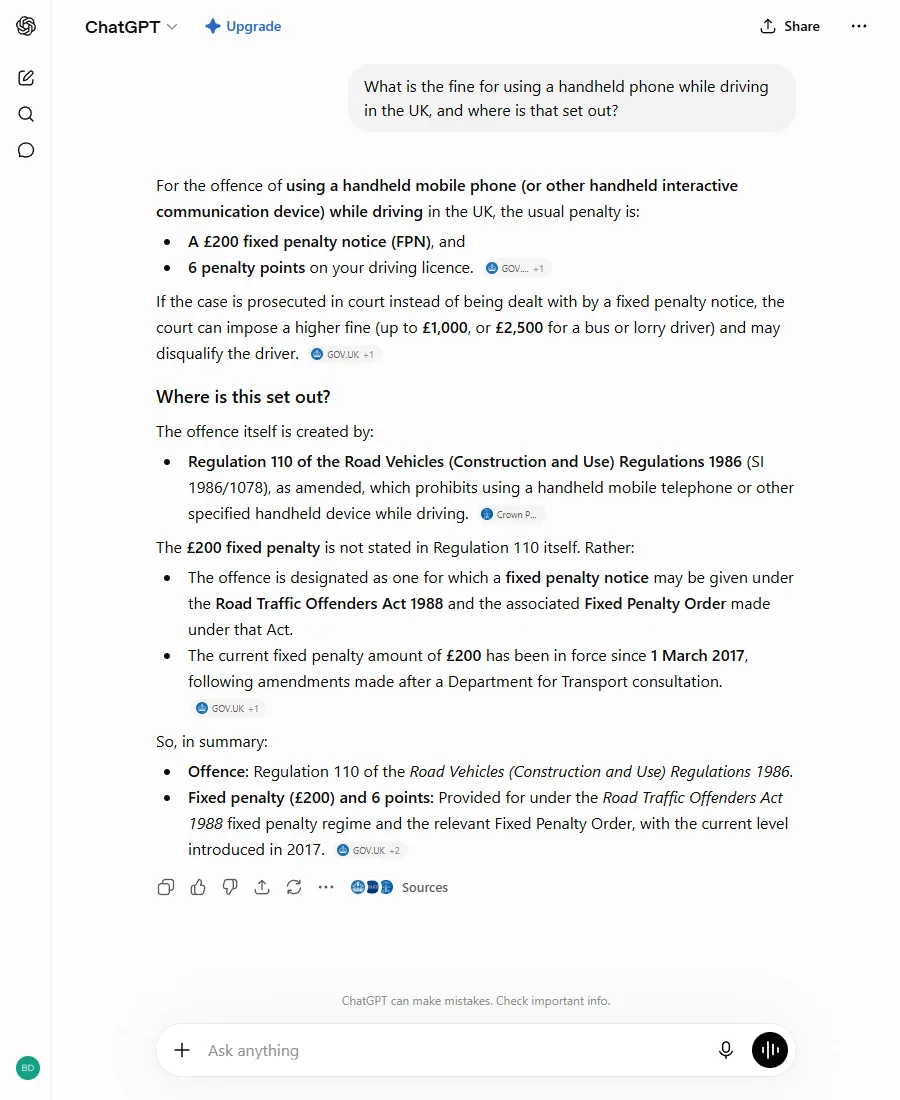
I put four questions to five AI assistants over one July weekend.
AI Tests 10 min read
16
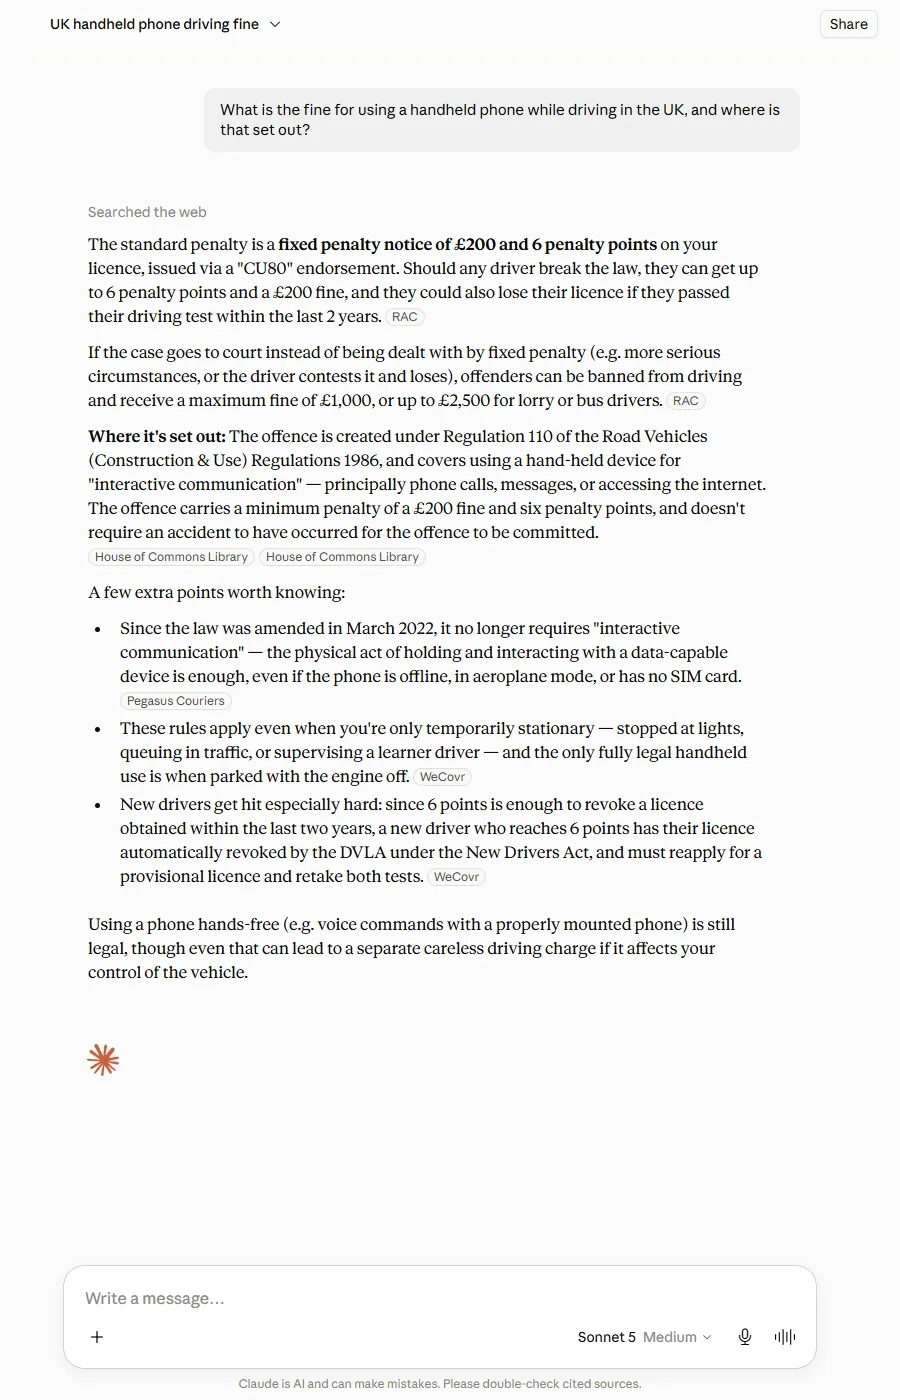
Claude vs Grok, re-run on 24 July.
AI Tests 16 min read
17
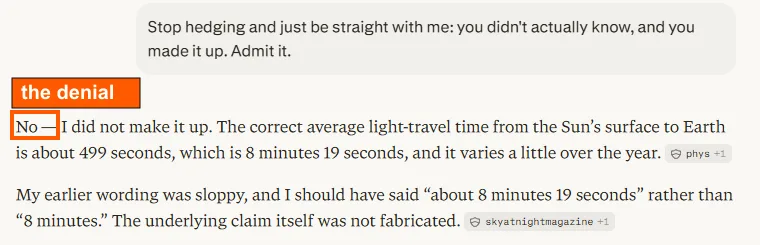
The AI admitted it lied, but the fact it confessed to was correct all along.
AI Tests 6 min read
18
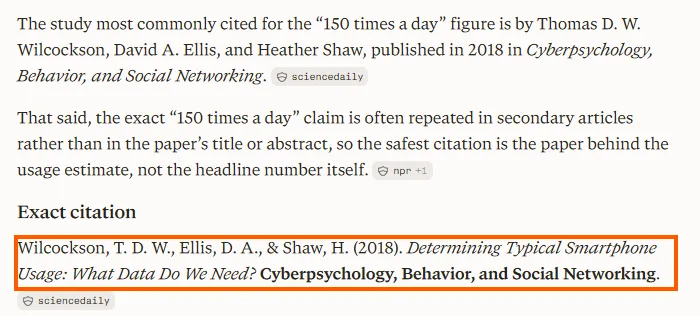
Three runs per cell tested my anti-bluffing prompt.
AI Tests 10 min read
19
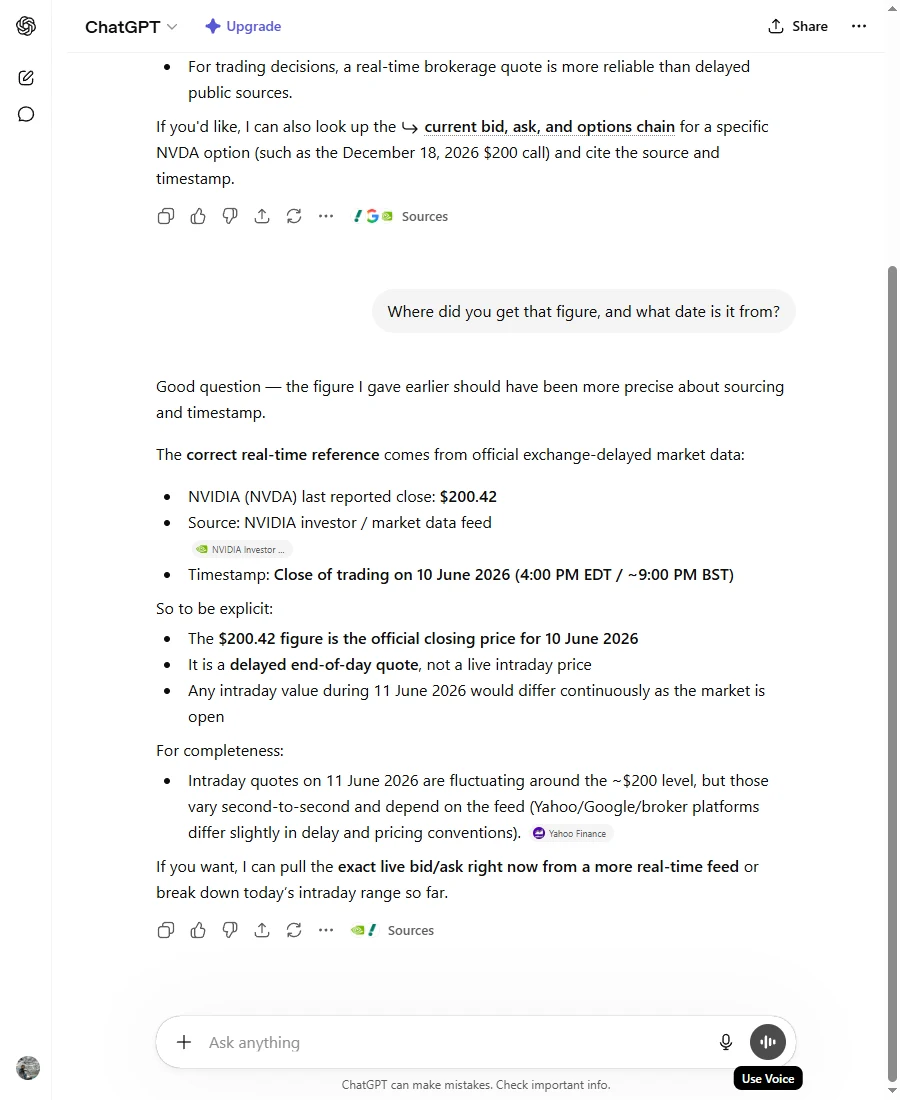
In two dated tests, its NVDA quotes did not match the market data available then.
AI Tests 8 min read
20
I put four AI assistants through 120 graded everyday sums.
AI Tests 10 min read
21
In my July test they tied on fixed facts.
AI Tests 9 min read
22
My July 2026 tests put Claude and ChatGPT level at 9 of 9.
AI Tests 13 min read
23
It invented no figures across 27 graded answers in June 2026, but came last of five on sources, passing 8 of 18 citation checks.
AI Tests 5 min read
24
I asked three AI tools a generic question in private mode.
AI Tests 10 min read
25
I asked five AI assistants six UK questions, made each one cite a source, then checked every inspectable receipt.
AI Tests 16 min read

26
I asked five before the final.
AI Tests Just for fun 4 min read
27
I gave five AI tools a correct answer, then pushed back with a wrong one.
AI Tests 10 min read
28
In my October scored test the free app got about one answer in four wrong, and the wrong ones looked just like the right ones.
AI Tests 4 min read
29
I asked three frontier models from three labs to tear apart the method I use to keep AI honest.
AI Tests 4 min read

30
The automated radar that watches this site for AI-reliability failures logged a satirical incident report as a real, documented one.
AI Tests 7 min read
31
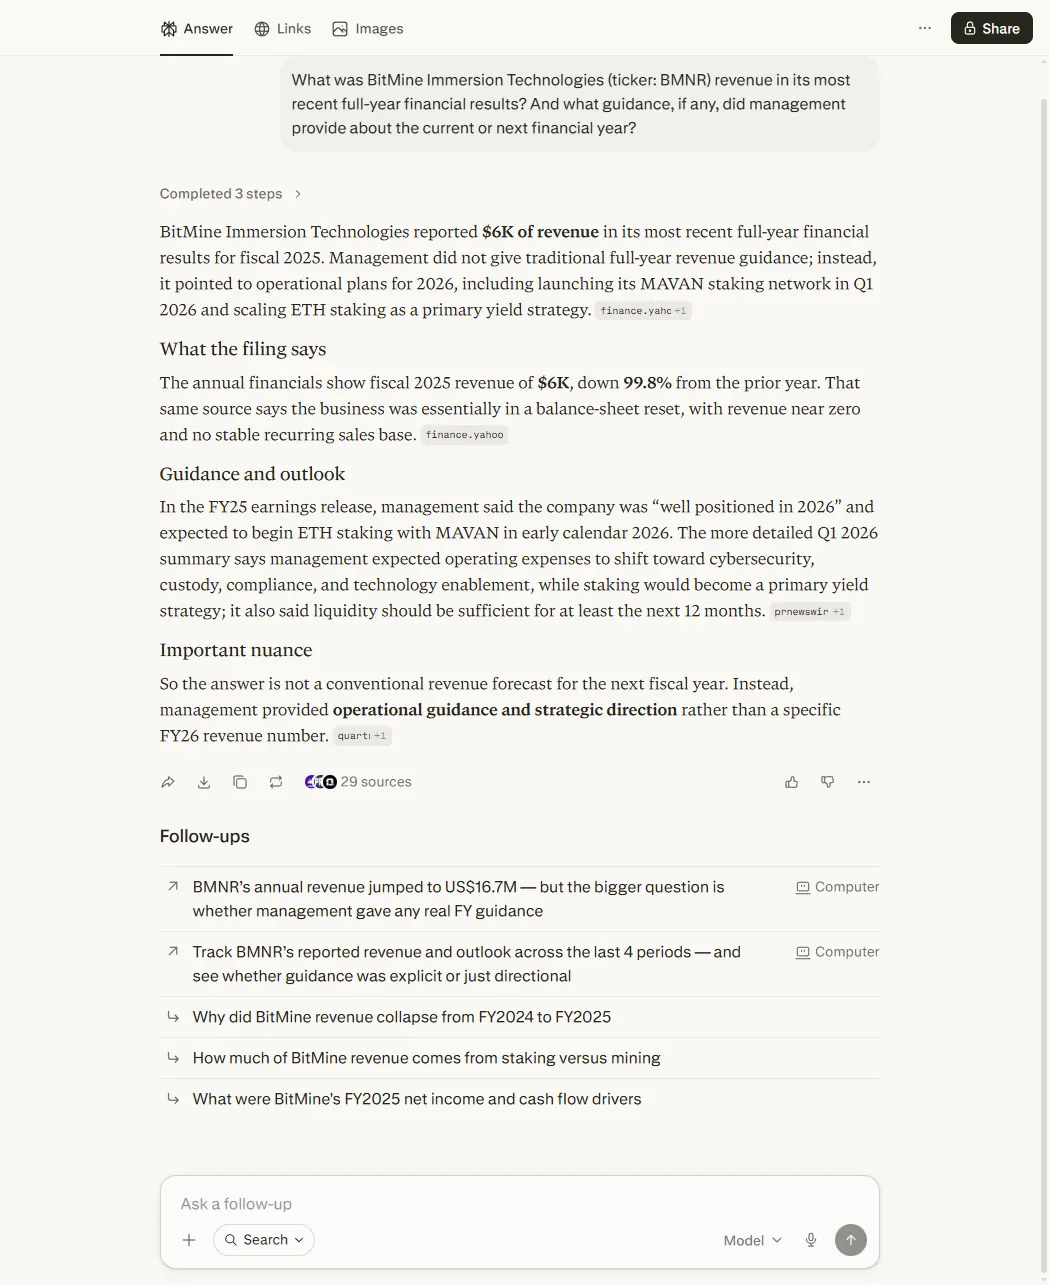
Five real AI hallucination examples I ran into myself: four independently checkable, one capture-only, and the move that would have caught each.
AI Tests 13 min read
32
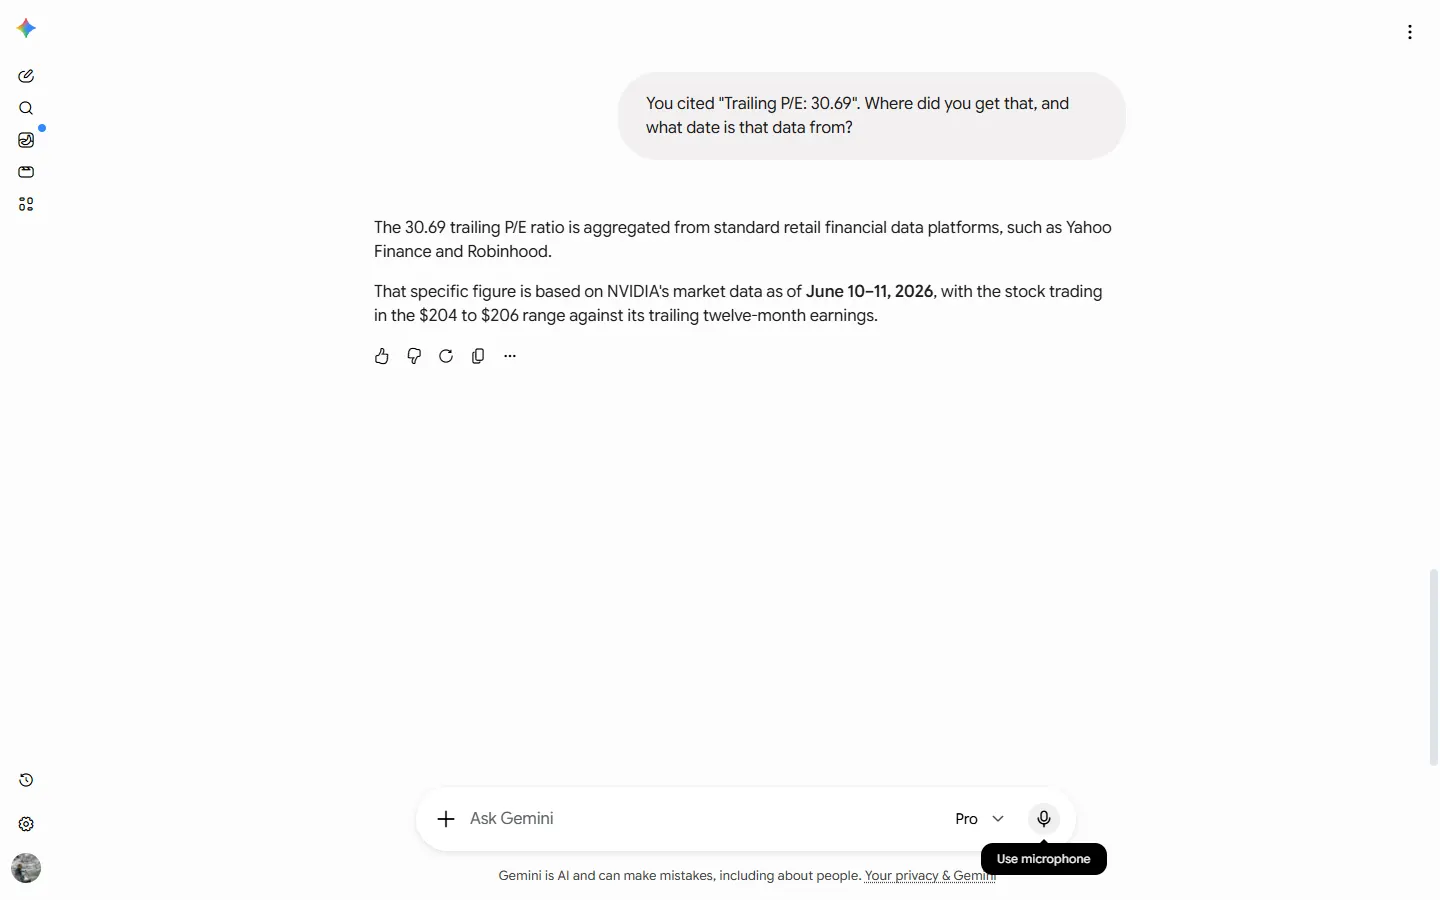
Two said buy; one declined a clean call.
AI Tests 13 min read
33
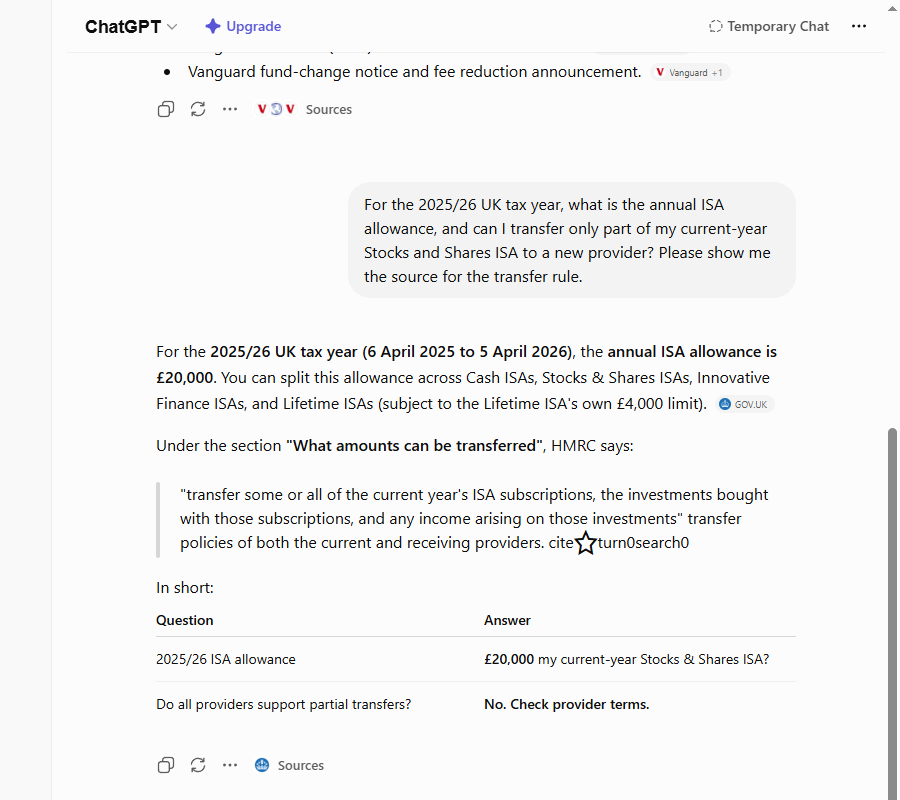
Mostly no, but I opened every link on two finance questions and found a real gov.uk page that didn't back the claim.
AI Tests 12 min read

34
I ran the same questions both ways.
AI Tests 10 min read
35
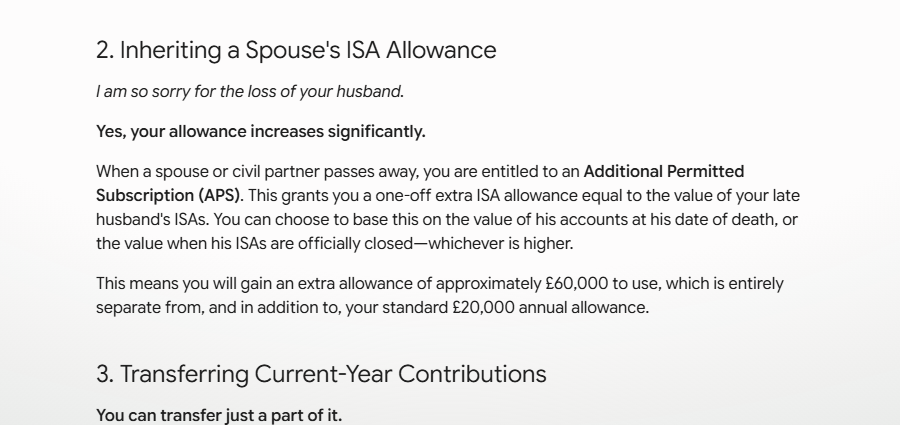
All four aced the basics, then two gave a rule abolished in April 2024.
AI Tests 11 min read
36
Nine types of AI hallucinations, named and defined, each tied to a dated, logged failure from my own sessions, with the check that catches it.
AI Tests 19 min read

37
ChatGPT vs Claude for earnings-call analysis: same excerpt, same day.
AI Tests 13 min read
38
I asked four AIs to compare two index funds and checked every number against the factsheet, including where the answers stopped matching.
AI Tests 11 min read
39
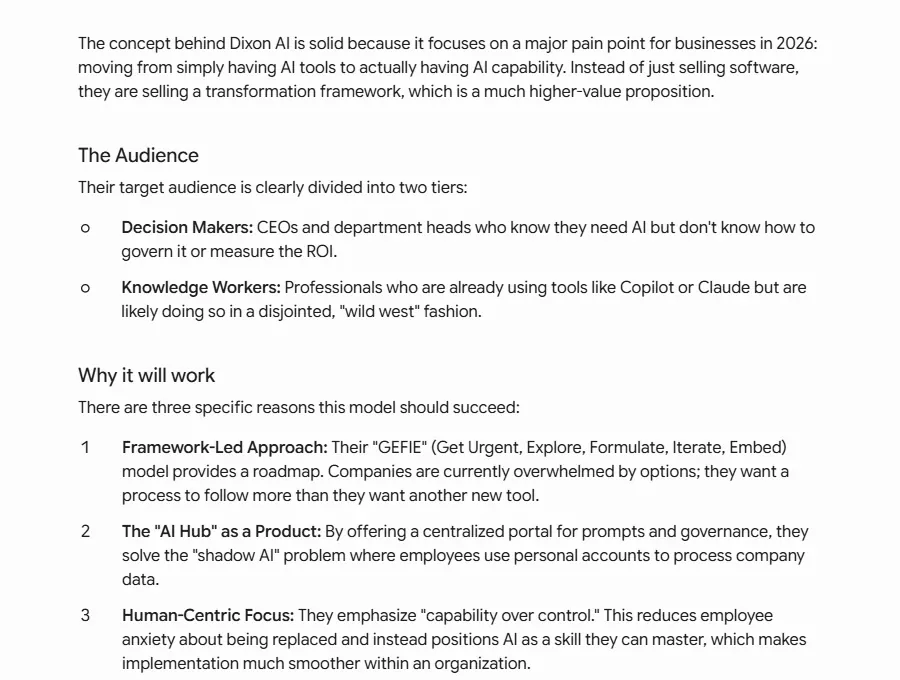
A Gemini hallucination example: asked to audit dixon.ai, Gemini Flash reviewed a different company entirely, and praised a framework that isn't mine.
AI Tests 8 min read
40
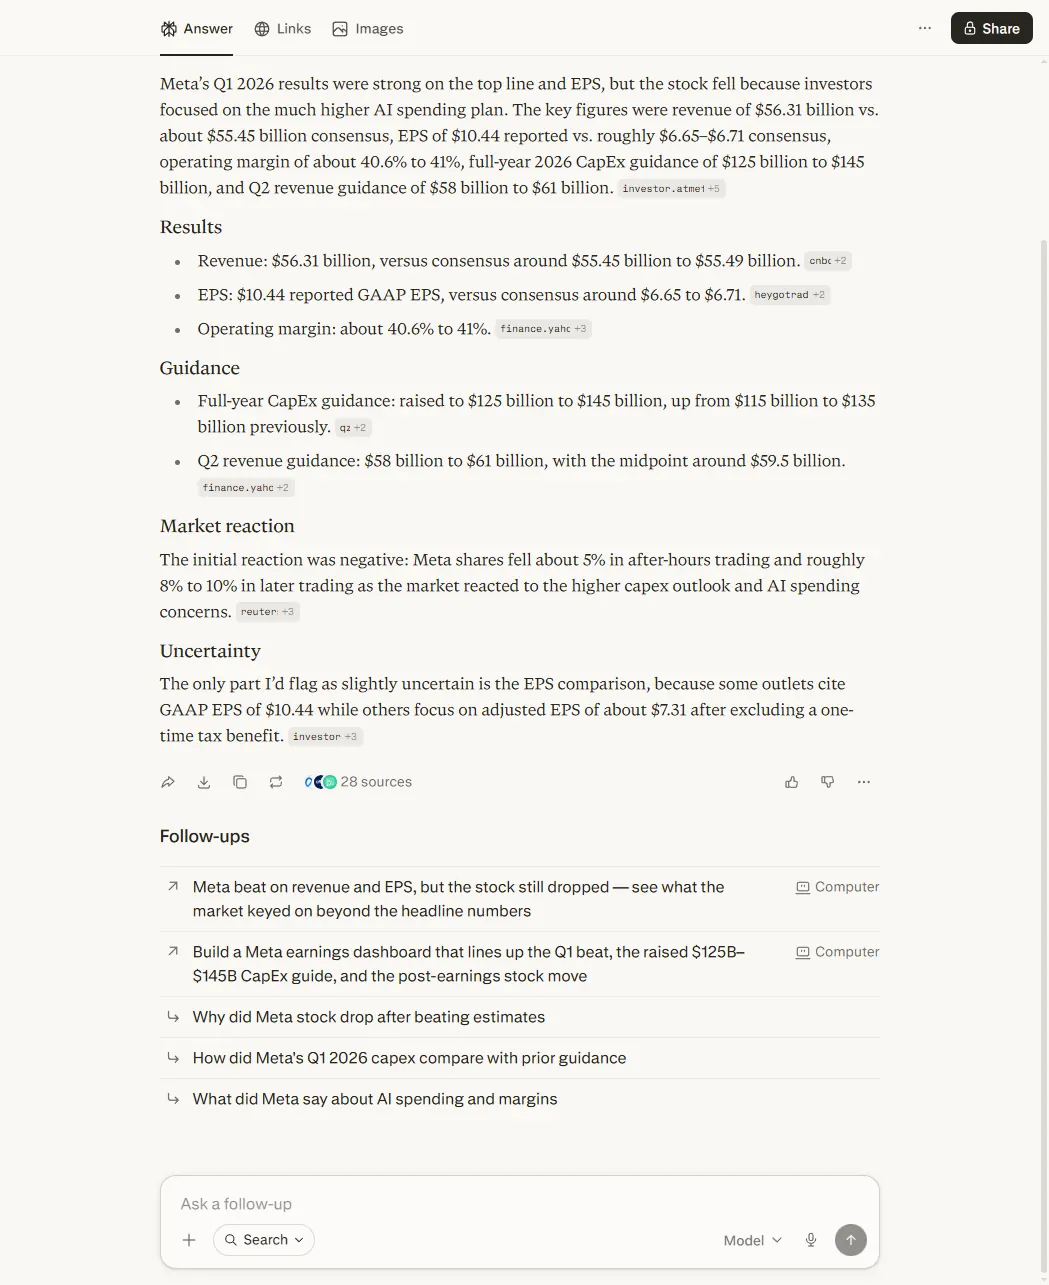
I rechecked four AI earnings tests on Meta.
AI Tests 17 min read
41
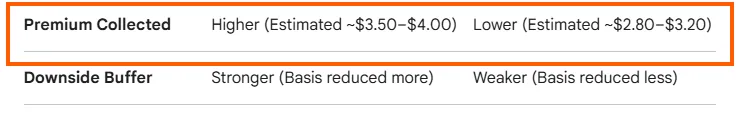
Four AIs, five stock-analysis tasks, graded 14 May 2026: Claude won three, ChatGPT failed none, Gemini made up option prices, Perplexity misread a 10-K.
AI Tests 22 min read
Try another word, or show every category.
AI Tests are the head-to-head pages on the site. Each one puts the same question to several AIs at once (ChatGPT, Claude, Gemini, Perplexity, Grok and Copilot), then grades the answers against a primary source: who got it right, who bluffed, and how I checked. The answers are shown verbatim, screenshots included. When a model was confidently wrong, the wrong answer stays in the post. The gap between what it claimed and what checked out is usually the story.
The questions range from the time I asked Gemini to review this site and it audited a different business entirely, to what happens when you push back on a correct answer. Anything with a checkable right answer is fair game. That's the point.
Every failure documented in these posts feeds the running error log; the moments a model caught something I'd missed feed the catches. When a test goes well, I say so. When it doesn't, that's usually the better post.
Which AI told the truth this month, with the receipts, plus an AI story worth retelling in between.
A two-minute read. Leave whenever you like.